
Enterprise infrastructure for every accelerated workload.
Three integrated platform lines — AI training, GPU virtualization, and high-performance computing — delivered as secure, observable, and elastically scalable services.
Train large models without wrestling infrastructure.
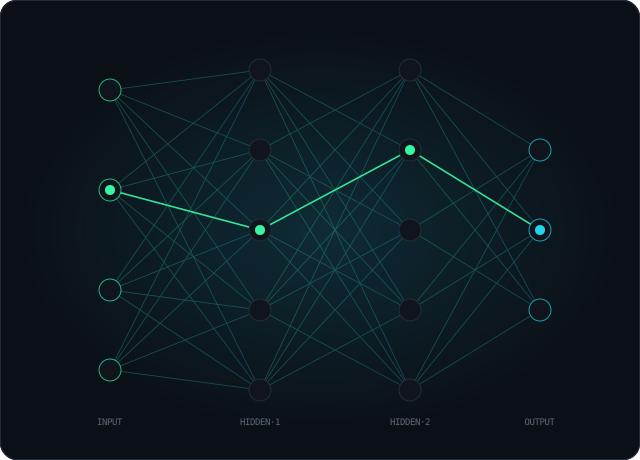
A managed accelerator cloud engineered for training large language models and complex neural networks. Provision multi-GPU nodes, scale to distributed multi-node runs, and rely on fault-tolerant checkpointing to protect long jobs.
- Distributed training orchestrationData- and model-parallel strategies with gradient synchronization over high-bandwidth interconnect.
- High-throughput data pipelinesShared parallel storage and caching that keep accelerators saturated during training.
- Framework-nativeFirst-class support for mainstream deep-learning frameworks and containerized environments.
Workstation-class performance, delivered anywhere.
Partition physical GPUs into virtual profiles and stream workstation-grade graphics to remote teams. Ideal for 3D rendering, CAD, simulation, and creative pipelines where local hardware is costly or impractical.
- Flexible GPU profilesFractional and full-GPU allocations mapped per user, session, or department.
- Low-latency remotingTuned protocols preserve interactivity for latency-sensitive design work.
- Central governanceUnified provisioning, session policy, and license management across the estate.
Elastic compute for data-intensive workloads.
Scheduler-driven HPC for scientific simulation, risk modelling, genomics, and large-scale analytics. Scale batch and tightly coupled parallel jobs across a low-latency fabric with throughput-optimized storage.
- Batch & parallel schedulingQuota-aware queues with priority, preemption, and burst scaling.
- Low-latency fabricHigh-bandwidth interconnect for MPI and tightly coupled workloads.
- Parallel file systemsStorage tuned for the sustained throughput HPC jobs demand.
Design your deployment with our engineers.
Share your workload profile and we will propose a reference architecture across AI cloud, vGPU, and HPC.